❌

Reading view

GSMA Open Gateway: MEO, NOS e Vodafone reforçam combate à fraude com novas APIs de rede

A MEO, NOS e Vodafone vão disponibilizar novas APIs de rede para ajudar empresas e organizações a reforçar a segurança dos serviços digitais e a combater a fraudes. As primeiras ferramentas permitem verificar identidades, detetar trocas de cartões SIM e identificar números de telemóvel que mudaram de utilizador.

The post GSMA Open Gateway: MEO, NOS e Vodafone reforçam combate à fraude com novas APIs de rede appeared first on Tek Notícias.

  •  

iPhone Duo terá suporte ao Apple Pencil no iOS 27.2; Alcançabilidade chegará em breve

O embargo de reviews do iPhone Duo caiu hoje e, com a enxurrada de análises do produto, temos algumas novidades sobre alguns recursos e acessórios.

De acordo com a WIRED, a função Alcançabilidade (Reachability) chegará ao iPhone Duo até o fim do ano. O recurso permite acessar os cantos esquerdo e direito da interface do sistema com um único toque, o que facilita o uso do aparelho (que tem um formato maior do que o dos iPhones convencionais) por quem tem mãos pequenas.

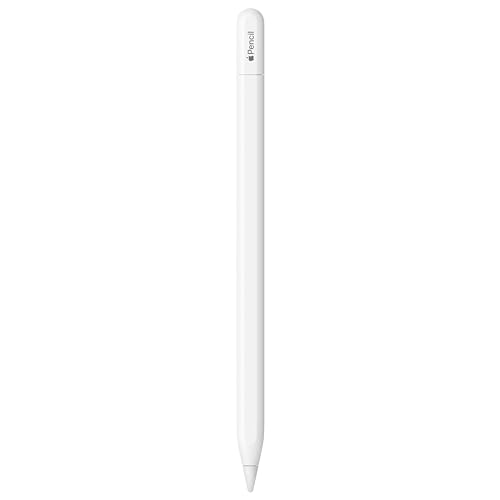
Já sobre o suporte ao Apple Pencil (restrito ao modelo USB-C), há uma boa notícia: o recurso virá junto com o lançamento do iOS 27.2, provavelmente na semana que vem.

Apple Pencil support is with iOS 27.2 btw

iOS 27.2 RC rolled out Monday, and it works pic.twitter.com/tt3QQbjkZv

— Max Weinbach (@mweinbach) October 21, 2026
O suporte ao Apple Pencil está no iOS 27.2, aliás.
A RC do IOS 27.2 saiu na segunda-feira, e funciona.

Como originalmente a Apple só havia mencionado que o acessório poderia ser utilizado no iPhone “ainda neste ano”, esperava-se que a novidade só chegasse com uma futura atualização (um pouco mais distante), mas o suporte virá mesmo em breve, para a alegria dos (poucos) felizardos que já estarão com o aparelho em mãos.

iPhone Duo

iPhone Duo

Cores: branco-estrela ou céu noturno
Armazenamento: 256GB, 512GB, 1TB ou 2TB
R$ 21.999,00
Apple Pencil (USB-C)

Apple Pencil (USB-C)

R$ 599,00
R$ 899,00

NOTA DE TRANSPARÊNCIA: O MacMagazine recebe uma pequena comissão sobre vendas concluídas por meio de links deste post, mas você, como consumidor, não paga nada a mais pelos produtos/serviços ao usar os nossos links de afiliado.

via MacRumors

  •  

★ Proteção completa para os iPhones 18 Pro/18 Pro Max, Duo e muito mais: cases premium, película, garantia de tela e Shokan Pencil com desconto!

Comprar um novo iPhone é sempre uma experiência especial — principalmente quando estamos falando dos recém-lançados iPhones 18 Pro, 18 Pro Max e do novíssimo iPhone Duo! Mas, junto com a empolgação de conhecer os novos recursos, surge também uma preocupação inevitável: como proteger um aparelho tão valioso sem esconder seu design ou comprometer a experiência de uso?

Pensando nisso, os nossos parceiros da Shokan Premium apresentam sua nova linha de capas desenvolvida especialmente para os novos modelos profissionais da Apple.

Mais do que um acessório, a capa representa a primeira linha de defesa do iPhone contra quedas, impactos, riscos e pequenos acidentes do dia a dia. Afinal, basta um único descuido para transformar a empolgação com o aparelho novo em uma grande dor de cabeça.

Proteção premium por todos os lados

As novas capas Shokan Premium foram desenvolvidas para proporcionar proteção, conforto e um acabamento à altura dos iPhones 18 Pro, 18 Pro Max e do novíssimo iPhone Duo, garantindo uma experiência realmente premium.

Cases da Shokan

Com encaixe preciso, construção resistente e design cuidadosamente elaborado, elas ajudam a proteger as laterais, a traseira, os botões e o conjunto de câmeras, preservando a aparência premium do iPhone sem deixá-lo pesado ou exageradamente volumoso.

É proteção para a rotina real: dentro da bolsa, sobre a mesa, durante o trabalho, em viagens ou naquele momento inesperado em que o iPhone escapa das mãos.

Capa, película e garantia de tela original

Para uma proteção ainda mais completa, a Shokan oferece uma condição especial que combina a capa premium com a película de proteção avançada da marca.

Além de ajudar a proteger a tela contra riscos, arranhões e impactos, a película Shokan conta com um grande diferencial: a sua garantia exclusiva de tela.

Película e aplicador da Shokan

Depois da compra e da ativação da garantia, caso ocorra um dano acidental coberto pelo programa, a tela do iPhone poderá ser substituída por outra original em um Centro de Serviço Autorizado Apple, conforme os termos e condições da garantia Shokan.

Enquanto a capa protege as laterais, a traseira e o conjunto de câmeras, a película cuida justamente da parte mais sensível e utilizada do aparelho.

É uma combinação pensada para quem deseja aproveitar o novo iPhone com muito mais segurança e tranquilidade desde o primeiro dia.

Você já comprou algum case nos Estados Unidos? E película?

A Shokan Premium é uma marca brasileira com produtos desenvolvidos nos Estados Unidos, então se você conhece as cases premium de verdade (como Incipio, OtterBox, Tech21, Speck, Balkin, Griffin e Prodigee), precisa conhecer a Shokan Premium. É uma marca pensada para quem realmente sabe o que quer em termos de qualidade e proteção — produtos com acabamento completamente diferente do que encontramos aqui no Brasil.

A proposta da marca é trazer produtos de qualidade superior com uma relação ótima de custo-benefício. Se compararmos, por exemplo, o preço de um case premium em uma Apple Store ou na Best Buy (que vai de US$69 a US$199), vale muito mais a pena comprar a proteção completa da Shokan e receber em casa.

Película da Shokan

Ah, e se você estiver nos EUA, a Shokan também entrega em todo o território pelos mesmos preços daqui.

Shokan Pencil: mais precisão para criar, trabalhar e estudar

Além da nova linha de proteção, a Shokan também oferece uma alternativa versátil para quem deseja ampliar as possibilidades de uso dos seus dispositivos Apple.

A Shokan Pencil é uma caneta capacitiva ativa e passiva, com bateria interna recarregável, ponta de alta precisão e excelente desempenho para atividades domésticas e profissionais.

Shokan Pencil

Ela pode ser utilizada para fazer anotações, desenhar, assinar documentos, editar imagens, navegar por aplicativos e executar tarefas que exigem mais controle e precisão do que o toque dos dedos.

Entre seus principais diferenciais estão:

  • Funcionamento ativo e passivo;
  • Bateria interna recarregável;
  • Ponta de alta precisão;
  • Formato confortável e ergonômico;
  • Ampla compatibilidade com dispositivos Apple elegíveis;
  • Uso profissional, criativo, acadêmico e doméstico;
  • Garantia e suporte especializado da Shokan no Brasil.

Com preço normal de R$499, a Shokan Pencil estará disponível por apenas R$399 para os leitores do MacMagazine, oferecendo uma excelente relação entre qualidade, desempenho e custo-benefício!

Cupom exclusivo, frete grátis e entrega expressa!

Para celebrar a chegada da nova geração, os leitores do MM terão acesso a condições especiais para adquirir os produtos Shokan. Ao utilizar o cupom exclusivo SHKMM, o cliente garante:

  • Desconto nos produtos participantes para toda a linha de iPhones;
  • Shokan Pencil de R$499 por R$399;
  • Frete grátis para todo o Brasil;
  • Entrega expressa pelo Mercado Envios;
  • Compra segura diretamente na Loja Oficial Shokan no Mercado Livre;
  • Garantia e suporte especializado da Shokan.

Cupom: SHKMM

Basta acessar a oferta, selecionar os produtos e o modelo correspondente ao seu iPhone e aplicar o cupom antes de concluir a compra.

Se você investiu em um novo iPhone 18 Pro ou 18 Pro Max, não espere a primeira queda para começar a pensar em proteção. Afinal de contas, quanto vale a sua tranquilidade?

E, se deseja mais precisão para trabalhar, estudar ou criar, aproveite também a condição especial da Shokan Pencil.

Proteja seu novo iPhone e amplie suas possibilidades com a qualidade da Shokan Premium

➡️ Capas e películas Premium de Verdade a partir de R$99
➡️ Shokan Pencil por R$399
➡️ Loja Oficial da Shokan no Mercado Livre com entrega grátis e FULL pro Brasil inteiro

Ofertas válidas por tempo limitado e sujeitas à disponibilidade de estoque. A garantia de tela está vinculada à película Shokan elegível, exige ativação e está sujeita aos termos, prazos, limites e demais condições do programa. Benefícios de frete e entrega são aplicados conforme as regras da campanha e do Mercado Envios.

Quer revender produtos Shokan na sua loja?

Se você é lojista do mercado mobile e tem interesse em revender a linha da Shokan, o distribuidor autorizado da marca no Brasil é a AllCell, que fica no DF. Entre em contato (+55 61 98354-0125; Alexandre) e tenha as melhores opções em acessórios premium para a sua loja!

  •  

OpenAI launches managed Agents API to simplify enterprise AI agent development

OpenAI on Wednesday introduced a new Agents API that brings the agent harness and infrastructure behind Codex to developers, potentially giving enterprises a way to build custom AI agents while removing much of the orchestration and infrastructure management traditionally required to make such agents work.

That reduction in engineering complexity is possible because the Agents API is a managed service, with OpenAI hosting and maintaining the underlying harness and infrastructure.

Previously, developers building a custom agent typically had to assemble the components needed to support its work, including an agent runtime, context and session management, tools and external data connections, execution environments, and associated infrastructure.

OpenAI itself already offers several of those building blocks through products such as its Responses API, which developers could use to combine models with built-in capabilities including web search, file search and computer use, and its Agents SDK for defining and orchestrating agent workflows.

Agents API, which is currently in public beta, in contrast, can help developers design a custom agent in a single API call after they specify the task, model, tools, and the environment, the model provider wrote in a blog post.

For that execution environment, developers can choose to run agents in an OpenAI-managed sandbox, on their own infrastructure, or through supported sandbox providers, including Blaxel, Cloudflare, Daytona, DigitalOcean, E2B, Modal, Oracle, Runloop, and Vercel, it added.

These options give enterprises flexibility to choose between fully managed environments and deployments within their own VPCs, as well as different approaches to file and secret storage and compute configurations based on their workloads, it further explained.

The API could reduce time to production

The Agents API “significantly reduces” engineering work, helping developers spend more time building the actual business application instead of the agent infrastructure, said Pareekh Jain, principal analyst at Pareekh Consulting.  

“The main advantage with the Agents API is fewer moving parts. A long-running agent built by hand needs a job queue, a state database, a sandbox fleet, a compaction routine and a retry policy, and someone has to own and page for each of them,” echoed Amit Kumar Jena, AI development head at IT consulting firm Kanerika.

That reduction in engineering work, in turn, could help CIOs reduce the time required to roll out an agent in production and subsequently scale it.

“Enterprises may need fewer engineers to build the infrastructure around each agent, which should reduce development time,” said Phil Fersht, CEO of HFS Research.

That time advantage, Jena said, could be critical for most enterprises as agent development usually stalls between a working demo and a system capable of running unattended for hours, with infrastructure-related issues often becoming the key bottleneck to moving an agent into production.

Convenience at the cost of lock-in?

The reduction in engineering effort and potentially faster path to production, however, does not eliminate the tradeoffs CIOs must consider, including greater reliance on OpenAI for both the underlying agent infrastructure and the models powering it.

“Lock-in is the biggest concern. If OpenAI provides the model, context management, tools, orchestration, and execution environment, moving to another platform becomes harder,” Jain pointed out.

That dependency could also weaken an enterprise’s negotiating position on pricing and terms, Jena said.

There are also issues around data privacy and governance as the new API “doesn’t support Zero Data Retention” even when enterprises use their own sandbox, Jena pointed out.

That, in turn, could limit its adoption, especially in industries in the regulated sectors, such as healthcare and BFSI, Fersht said.

Rather, Startups, SaaS companies, and enterprises already using OpenAI are more likely to adopt the new API more readily as it reduces development effort, Jain said.

“Enterprises pursuing multi-model strategies may also prefer their own independent harness or are likely to take a hybrid approach,” Jain added.

Agents API’s adoption could be further limited due to the competition it faces from hyperscalers and rivals, analysts pointed out.

“This is a crowded category. Anthropic’s Claude Managed Agents has been in public beta since April. AWS also offers Amazon Bedrock AgentCore, whose managed harness became generally available in June and does the same category of work, meaning the loop, tool execution, context, state, and recovery, while letting you use any model and switch providers mid-session without losing context,” Jena pointed out.

Other competing offerings include Microsoft’s Foundry Agent Service and LangGraph, Jena added.

  •  

Why enterprises should start with on-site AI agents

When I talk to people about agents interacting with websites, the conversation almost always starts with perception: how does an agent “see” a page? Is it screenshots or the DOM or the accessibility tree? In my previous InfoWorld article, “Accessibility is the first-class interface for AI agents”, I argued that the accessibility tree is becoming an increasingly important interface between websites and AI agents. From there the conversation shifts to actuation, and to ways of making it less brittle, which let a site expose its own actions as callable tools instead of forcing an agent to guess at buttons and forms.

That conversation matters. But it leaves out a more consequential architectural question, one that determines who is accountable when an agent gets something wrong: where does the agent live?

There are three plausible homes for an agent that interacts with your business: on-site, in-browser and off-browser. Each one trades control for reach differently. Right now, much of the industry’s attention is focused on the two homes furthest from the business: browser extensions that co-browse alongside a user, and autonomous agents running in the cloud that talk to your APIs or drive a browser on their own.

I think that is the wrong place for most enterprises to start.

If you run a business with real compliance exposure, or a brand you cannot afford to have misrepresented, the pragmatic move is to build the agent that lives on your own site first and treat reach as a problem you solve later, on your own terms.

Reach without governance is a liability

The appeal of in-browser and off-browser agents is obvious. They promise discovery, scale and automation you do not have to build or maintain yourself. An off-browser agent can compare your prices against every competitor and keep working after your support team has gone home. A co-browsing extension can act inside a user’s already authenticated session without requiring any special integration on your side.

But an agent you do not control is still speaking for your business.

An off-browser agent talking to your APIs or scraping your DOM runs on a model you did not choose, follows guardrails you did not write and represents your brand in a conversation you cannot see. If it misquotes a price, misstates a policy or initiates a transaction that creates a customer dispute, the fact that the agent belonged to somebody else may not make the resulting problem disappear.

There is also a deeper security problem. Computer-use agents interact with untrusted content by design. Anthropic’s guidance for browser and computer-use agents notes that webpages and application interfaces can contain adversarial instructions and recommends scoped permissions, human confirmation for high-stakes actions, and monitoring of agent behavior. OWASP’s AI Agent Security Cheat Sheet goes further, identifying agent-specific risks including prompt injection, tool abuse and privilege escalation, data exfiltration and memory poisoning.

In-browser agents are a better deal, because a human is watching the same screen and can catch a mistake before it lands. But the model, the tone and the decision logic are still outside your hands. For  or any other regulated industry, that is not a risk to take lightly just to pursue reach you have not yet learned how to govern.

What you actually gain by building at home

An on-site agent is less glamorous than the idea of your product being discovered by roaming agents across the open web. But it is the only home where the business keeps full governance.

You choose the model. You define the guardrails. You decide the tone, the escalation paths and exactly what the agent is and is not allowed to promise a customer. Because the agent has direct access to your systems, it does not need to reverse-engineer your checkout flow as an outside agent would. It can be given your actual domain knowledge and your actual APIs.

That matters because enterprises have solved this problem before. They did not expose databases directly to the internet; they introduced APIs. APIs were not just about integration. They created contracts, authentication, auditing and policy enforcement. On-site agents represent a similar evolution. Rather than forcing an external agent to infer behavior from a user interface, a business can expose governed capabilities through tools with explicit contracts.

WebMCP is a promising step in that direction. It makes it easier for a site to publish actions an agent can invoke, instead of forcing the agent to guess at the page. The important shift is not that the agent can click a button. It is that every action becomes observable, policy-governed and replayable.

The Chrome team’s WebMCP Sports demo is a good preview of what this can look like done well: an on-site assistant calling the site’s own WebMCP tools, with every call visible in the chat log. That is not a black box you are hoping behaves. It is an auditable interaction, with named tools and defined contracts.

The three homes

The cleanest way to think about this is as a spectrum.

  • On-site. The agent lives on your website. You ship it. You own the model, the tools, the tone, the policies and the telemetry. It has first-party access to your systems and your workflows. The trade-off is reach: it is coupled to your site, and it is not meant to carry the user’s journey across the web.
  • In-browser. The agent lives inside the user’s browser session, usually as a co-browsing extension or a browser-integrated assistant. It benefits from the user’s logged-in state and can act with the user present. That gives it real reach and a strong human safety net. But the business does not control the model or the guardrails, and the agent can still misrepresent the brand.
  • Off-browser. The agent runs elsewhere — in the cloud, on a server or on a user’s local machine and reaches your business by talking to APIs or driving a browser remotely. This is the widest-reach model, but also the least governed from the business’s point of view. It may compare competitors, cross workflows and act at scale, but you do not control the experience.

None of these homes is inherently bad. They solve different problems. But if your first priority is governance, accountability and brand integrity, on-site is the right starting point.

Start with the governed interface

For teams deciding where to put their first investment, three moves make the difference between a real interface and a chatbot glued to a homepage.

First, ship the on-site agent as the authoritative interface, not a fallback. It should have first-class access to your own APIs and domain knowledge — the same systems your support team and checkout flow already use — rather than being handed a scraped version of your own page.

Second, instrument every tool call it makes. If your agent calls a WebMCP tool to check inventory or apply a discount, log it the way you would log an API call from any other client. That log is your audit trail, your debugging tool and eventually your evidence when a regulator or customer asks what happened.

Third, design for human escalation from day one. Even a well-governed agent should not make every decision autonomously. Build explicit handoff paths to human operators for ambiguous or high-risk situations.

Taken together, those choices turn an on-site agent into a governed interface rather than a novelty feature. That distinction matters. The first is something an enterprise can safely operate; the second is something it will eventually have to defend.

When agents start talking to agents

There is another reason to build the on-site agent first: the three homes are unlikely to remain isolated.

Imagine that a user’s browser agent arrives at an airline website. It already knows the traveler’s preferences, calendar constraints, loyalty programs and perhaps their budget. The airline’s on-site agent knows something completely different: routes, seat availability, fare rules, upgrade eligibility and the airline’s operational policies.

Why should the visiting agent reverse-engineer all of that from a website?

A more natural architecture may be for the two agents to communicate.

This is no longer purely hypothetical. The Agent2Agent (A2A) protocol is explicitly designed to allow independent agents built by different vendors and frameworks to discover capabilities, exchange information, delegate work and coordinate tasks.

In that world, the user’s agent brings intent and user context. The site’s agent brings domain knowledge and governed execution.

And suddenly the on-site agent’s limited reach does not look quite so limiting. It does not need to travel across the web if other agents can come to it.

The incentive problem nobody is pricing in yet

There is a harder question underneath the technical one: who does the on-site agent actually work for?

A visiting agent, co-browsing or otherwise, is acting on the user’s behalf. An on-site agent, however well-built, is the business’s employee. And the moment the two negotiate a discount, an upgrade or a substitution, that exchange stops looking like a neutral handoff and starts looking like a sales conversation with an AI on each side of the table.

That tension is going to matter.

Businesses building on-site agents now should design their guardrails with that scrutiny in mind, rather than treating “the agent decided” as a shield. Control is worth having. It is also a responsibility. And building the agent that answers to you is the only way to exercise it.

The first agent should be the one you can govern

The history of enterprise software suggests a familiar pattern. Organizations adopt new interaction models by first bringing them under their own governance. Internal systems become APIs. APIs become platforms. Platforms become ecosystems.

AI agents will likely follow the same path.

That is why I think the first agent your business builds should not be the one that can reach the entire web. It should be the one whose behavior you can understand, measure and improve. Once that foundation exists, expanding outward becomes an architectural choice instead of a leap of faith.

Reach is tempting. But for regulated and brand-sensitive businesses, control has to come first.

  •  

MacVoices #26248: AI Development: Start Small, Learn Safely, Then Build Bigger with Adam Engst (3)

Adam Engst explains why AI software development should be approached as an evolution, starting with safe, verifiable data analysis, advancing to simple scripts, and eventually building applications. He distinguishes programming from development, arguing that non-programmers can act as product managers who direct AI, demand security checks, define requirements, and create software tailored to problems existing apps do not solve. (3) 

💾

💾

  •  

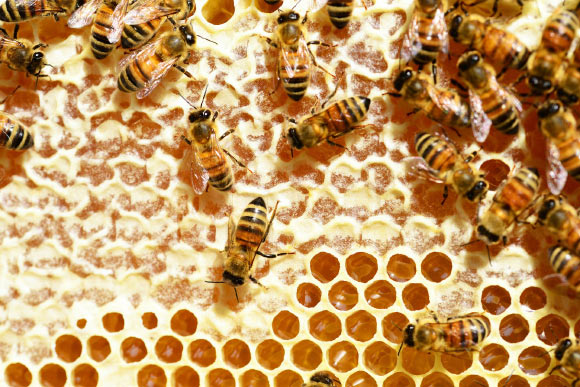
Some of Smallest Bee Species See Best, New Study Finds

The blue-banded bee Amegilla murrayensis. Image credit: Callin Switzer.

According to a new paper published this week in the Proceedings of the National Academy of Sciences, some of the smallest bees studied have photoreceptors as sharp as those of much larger honeybee drones.

The post Some of Smallest Bee Species See Best, New Study Finds appeared first on Sci.News: Breaking Science News.

  •  

OpenAI drops GPT-5.6 Luna and Terra API prices by up to 80%

OpenAI has cut API prices for its GPT-5.6 Terra and Luna models by 20% and 80%, respectively, while also reducing the number of usage credits the models consume in ChatGPT Work and Codex, in an effort to effectively increase the amount of AI work enterprise subscribers can perform without paying more.

“Starting July 30, API pricing is $2 per million input tokens and $12 per million output tokens for Terra, and $0.20 per million input tokens and $1.20 per million output tokens for Luna,” the company wrote in a blog post.

Prior to this update, enterprise customers paid $2.50 per million input tokens and $15 per million output tokens for GPT-5.6 Terra. For Luna, pricing stood at $1 per million input tokens and $6 per million output tokens.

These lower prices and effective reduction in credit consumption, OpenAI said, are the result of improvements in serving efficiency that allow it to deliver “more intelligence per dollar” for its most advanced family of AI models.

The efficiency gains, the company added, stem from optimizations across its AI training and inference stack, including software and GPU infrastructure, with GPT-5.6 Sol helping optimize production GPU kernels used to run AI workloads and reduce inference costs without compromising model performance.

Enterprises likely to spend differently, not less

Analysts say the price cuts are less about reducing enterprise AI spending and more about lowering the cost of deploying AI at scale.

“For CIOs, the biggest impact is likely to be scaling AI adoption rather than simply cutting costs or lowering AI budgets. Lower prices make it easier to move pilots into production, expand AI across more employees and business processes, and economically deploy more complex agentic workflows that require multiple model calls,” said Pareekh Jain, principal analyst at Pareekh Consulting.

“Instead of shrinking AI budgets, most enterprises will reinvest the savings into higher AI usage, allowing agents to perform more reasoning, automation, and multi-step workflows while delivering more business value for roughly the same spend,” Jain noted, saying the likely outcome reflects the Jevons paradox, the economic principle that efficiency improvements often increase overall consumption of a resource rather than reducing it.

Echoing Jain’s view, Chandrika Dutt, research director at Avasant, pointed out that enterprise teams are likely to use the leeway from the pricing change to build increasingly sophisticated agentic workflows that were previously difficult to justify economically.

CIOs need flexible AI architectures to benefit

More broadly, CIOs should view OpenAI’s pricing update as yet another sign that inference costs are likely to keep falling over the next 24 months across model providers, such as Anthropic, Google, and Microsoft, with a sharp increase being unlikely.

“These price decreases are broadly sustainable in the long run. New chips, better software, and more efficient model designs will keep driving down the cost per token, and heavy competition makes big price hikes risky for any single provider and thus unlikely,” Jain pointed out.

For enterprises and their leaders, that should mean designing AI strategies that prioritize AI FinOps and flexible architectures so models can be swapped as price-performance continues to improve across vendors, Jain added.

The larger and more advanced model in the GPT-5.6 family, named Sol, though, is not undergoing any pricing changes. Instead, OpenAI has introduced a new Fast mode for the model, replacing Priority Processing in the API. Existing API requests tagged “priority,” though, will continue to work, it added.

  •  

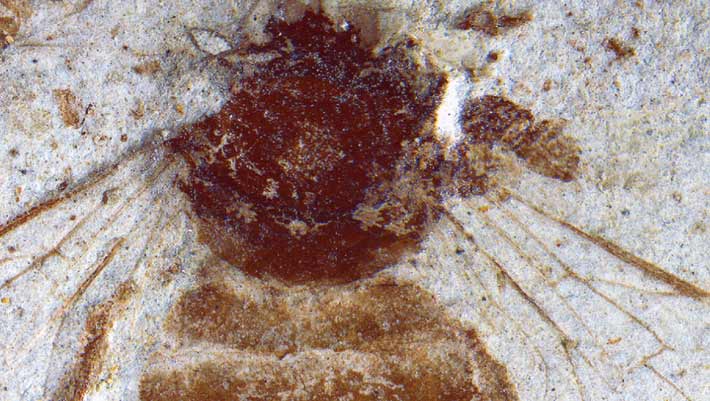
Japanese Fossil Bee Fills Two-Million-Year Gap in Honeybee History

Apis aibai. Image credit: Y. Takahashi & J-ichi Takahashi, doi: 10.3897/zookeys.1255.162389.

Paleontologists have announced the discovery of a new fossil honeybee species that fills a long-standing gap in the evolutionary record of the genus Apis.

The post Japanese Fossil Bee Fills Two-Million-Year Gap in Honeybee History appeared first on Sci.News: Breaking Science News.

  •  

How fuzzy APIs are remaking the web

For nearly as long as the web has existed, web development has wrestled mightily with the right way to connect components over the network. This is the question of the remote API. It influences every aspect of the software we build. We sort of arrived at a tolerable compromise with JSON APIs. While these have their limitations, you have to appreciate their underlying simplicity.

But the advent of AI-enabled endpoints that can mediate intent is changing the basic workings of the internet. This change is gradually reawakening an old dream, the service-oriented architecture (SOA). This time around, with luck, we’ll finally gain the flexible, discoverable, and maintainable automated service discovery we’ve longed for. Fingers crossed.

Why old-school SOA failed

Let’s call this burgeoning influence of AI on web architecture SOA 2.0.

To understand why SOA 2.0 is different from SOA 1.0, we have to remember the trauma of the 2000s. (This may be painful but also cathartic.) The original dream of SOA was beautiful: a world where disparate business services—inventory, billing, shipping, you name it—could automatically discover each other, understand capabilities, and orchestrate complex tasks without human intervention.

To achieve this, we built a monument to complexity. We had SOAP (Simple Object Access Protocol) for messaging, WSDL (Web Services Description Language) to define contracts, and UDDI registries for service discovery. At the center of it all sat the Enterprise Service Bus (ESB), a massive piece of middleware that was supposed to route everything gracefully, seamlessly. In case you young’uns are confused, that is all based on XML.

By the time you were done understanding the infrastructure well enough to know how to do something, you had forgotten what you set out to do.

It failed. It was egregiously heavy. Just to do some simple thing like create a “New Item” endpoint, you immediately had to begin scaling a wall of rigid definitions.

Because computers historically required absolute, deterministic perfection, if a single XML tag in a SOAP envelope was missing, or if a service updated its WSDL without every client re-generating its stubs, the entire multi-million-dollar pipeline would violently unravel. Some of us may be familiar with a similar challenge in containerized microservices (like Kubernates), where trying to determine where in the mesh a problem originated is… awkward.

Classic SOA was a house of cards, too brittle to survive the fuzzy reality of the internet.

The typical JSON API of today is a reaction against SOA. (It may be an overreaction.) We abandoned SOA for the relative simplicity of REST, giving up on the dream of autonomous service orchestration in exchange for manual integrations that just work.

The new intention-to-execution middleware

A sea change is already happening with app-level architecture. 

The effect of AI endpoints in an app’s service profile goes beyond just a new capability. It changes how the rest of the services work together. The overall effect is something like the app gaining an understanding of itself, and what it can do. This is not dissimilar to what WSDL was supposed to accomplish. But instead of a hard-coded descriptor, where some person had to keep what was available and what was described in sync, you now have a layer that can accept dynamically produced descriptors and unite them with fuzzy user intention and produce meaningful action.

You tie in AI endpoints to bridge between what the user is trying to accomplish, with the various strict capabilities available. These capabilities may exist within the app at the back end, at the front end, or at another service layer. The main thing is that there is a flexible AI layer that mitigates the need to hard-code the links between services.

In classic SOA, the contract was a rigid, unforgiving WSDL document. In modern common practice, the contract is a strongly coupled RESTful endpoint. In SOA 2.0, the contract has a hitherto unknown degree of flexibility, thanks to the natural language capabilities of an LLM.

When a user or a system expresses an intent—say, “Provision a new staging environment for the billing service”—the AI middleware doesn’t look for a hard-coded, point-to-point integration. Instead, it digests the intent and performs semantic routing, consulting a registry and selecting the appropriate tools. That registry, rather than a heavy UDDI, might be a vector database of available internal API endpoints, or a collection of available functions.

Modern LLMs equipped with function-calling capabilities act as the ultimate dynamic orchestrators. They read the JSON schema of a target REST API, understand its parameters, and dynamically map the user’s fuzzy, unstructured intent into a perfectly formatted JSON payload. If a field is missing, the LLM can either infer it from context or pause execution to ask the user for clarification.

The brittleness of SOA 1.0 is replaced by a shock absorber. If the target API changes a parameter name from customerID to clientId, the AI middleware can read the updated schema and adjust its mapping on the fly. No client code needs to be recompiled. No stubs need to be regenerated. The multi-million-dollar pipeline survives.

When software becomes smart

These are not just abstract ideas. I recently did my taxes, using a popular mainstream service that I will not name. I had several unusual and grumpy areas to deal with, including the new crypto regulations. It was not pretty.

But what I was most struck by was how dumb the software was, compared to the AI chatbot I was using to help guide me. I wanted to be able to tell the (stupid) software what I was trying to do. Such as “Carry my NOL from last year!” Or “I don’t know if I need a schedule K, you tell me!”

I don’t want another chatbot. I mean, I already have a good chatbot. I want the application to be well-integrated with AI services that understand the app, understand my current situation within the app, and meet me at the level of intent, applying the lessons learned by others who have used the same tools.

This kind of targeted, intelligent leveling up of intention is, from all I can see, the next stage of software development, and it is going to be massive.

Latency, non-determinism, and other challenges

We are trading the deterministic brittleness of classic SOA for the probabilistic fuzziness of SOA 2.0. And that trade is going to be demanded with ever more insistence by users. But it comes with a new set of trade-offs.

First, there is the latency tax. The old enterprise service bus was heavy to configure, but at run time, the messaging was just routed XML. Injecting an LLM into the critical path of an application adds hundreds of milliseconds, if not seconds, of latency. For asynchronous tasks or complex orchestrations, this is a welcome trade-off. For real-time, high-throughput microservices, it is a deal-breaker.

Second, there is the problem of non-determinism. We spent decades training ourselves (and our systems) to expect that given input A, a system will always produce output B. That deterministic equation was our bottom line faith. The intent layer doesn’t work that way. An LLM might route a request beautifully 99 times, then hallucinate a parameter on the 100th. Or it might choose an entirely different execution path based on a subtle shift in the user’s phrasing.

A third fly in the ointment is the so-called non-functional requirements, or NFRs. These are your pesky sidebar issues that refuse to be ignored, like security and reliability. 

Security concerns are magnified by model capabilities like function calling (or “function passing”). If you pair a user’s desires with what the AI can do, and you then let the AI decide, what happens next is clearly an act of faith unless guardrails are put in place. These guardrails must go beyond typical web security (i.e., make sure important function calls are hardened on the server, not exposed on the client) and must be internalized by the AI or (more likely) imposed from a layer outside the AI. There are a number of ways to do this, varying in degree of power and complexity. 

We certainly will continue to use standard practices (like RBAC and SSO) to enforce authentication. We will continue to implement standard authorization techniques (like OAUTH and JWT). But we will bring these to bear in the context of that intent layer and its capabilities.

Reliability is another challenge. For example, I recently hit a snag with Google’s Imagen API. Everything was working beautifully, then suddenly, some of the images stopped generating. There were no errors in the client or server logs; however, there were 500 errors in the network. Upon deeper examination, the prompting had morphed (between app context and user content) to include what the Imagen API rules deemed to be dangerous content. This was not obviously flagged prompting. It was fairly pedestrian creative writing, along the lines of “A dark, surreal, and glitchy cyberpunk landscape with menacing figures….” That kind of thing.

These are some of the ways that even simple, direct use of LLM APIs can surprise you. The question I am mulling is, what will be the unexpected outcomes on software writ large?

Dawn of a probabilistic web

Since its inception, the unpredictable, probabilistic nature of the internet came primarily from the humans using it (and background radiation flipping transistors, network failures, geopolitical effects on the ground, and the like). But AI-mediated APIs introduce an intentional, semantically controlled form of probability.

As developers, we will naturally discover the techniques that make consuming AI endpoints more effective. Here I am thinking about practices like structured responses and function calling. But the larger question is, what will the nature of software become?

In a world of binary states, strict protocols, and rigid URIs, if you send a GET request to a specific endpoint, you expect an exact, predictable response. We have spent the last 40 years treating the web like a vast, unimaginably complex state machine.

But as LLM-mediated APIs permeate our architecture with stochastics, the very fabric of the internet begins to change. By injecting AI into the routing and discovery layers, we are introducing a massive dose of probability into the foundation of our networks. When a request is no longer a hard-coded URI call but a natural language intent parsed by an LLM, the connection between node A and node B ceases to be a rigid wire. It becomes a weighted probability.

In essence, we are remaking the internet to mirror the architecture of the AI models we are deploying. Just as a neural network relies on the probabilistic firing of synapses rather than deterministic if/then statements, the next iteration of the web will rely on fluid, semantic discovery. Services won’t just “link” to each other; they will gravitate toward one another based on the conceptual proximity of their capabilities within a shared latent space.

This alters the character of software engineering. We lose (the illusion) of being entirely in control. Its strange paradox is that engineering using explicitly probabilistic components may make for a more resilient system. There is a longstanding debate about the best metaphor for software development. For the longest time, the construction of a building always seemed to be an apt analogy, or perhaps the mechanics of a vehicle. But these days, the gardening or cultivation metaphor is looking ever more relevant.

Despite the challenges posed by inserting AI in the stack, we are finally circling back to the original promise of the early 2000s. This time, fingers crossed, we are equipped with the right tools for the job.

We tried to build autonomous service discovery using rigid logic and deterministic XML, and it collapsed under its own weight. Now, we are building it with neural networks that understand the “intent” behind the integration. We are still building middleware, but instead of an enterprise service bus, we are building an enterprise reasoning bus.

The era of manually hard-coding every integration between every microservice may be coming to a close.

  •  

MEO aposta em APIs de rede 5G para reforçar autenticação e prevenção de fraude em setores críticos

A MEO desenvolve e disponibiliza APIs standard de rede móvel 5G para autenticação aplicacional, prevenção de fraude e proteção de transações críticas. Esta aposta conta com a parceria da Nokia, Infobip e Aduna.

The post MEO aposta em APIs de rede 5G para reforçar autenticação e prevenção de fraude em setores críticos appeared first on Tek Notícias.

  •  
❌