❌

Reading view

He Wants AI Benchmarking To Be a Science, Not a Dark Art

Benchmarks are the rulers of AI, in both senses of the word. As measuring sticks, they work according to an extremely simple logic: If you want to know what an AI model can do, devise a standardized test to gauge it. But AI benchmarks can also dominate the behavior of the entire field. In 1987, the Defense Advanced Research Projects Agency’s first benchmark on automatic speech-to-text…
Source

  •  

Is AI Reasoning Right for the Wrong Reasons?

I’ll just say it: What the hell is going on with AI β€œreasoning”? Sorry for the air quotes. That punctuational side-eye was more common in 2024, when the specially trained cousins of LLMs now known as β€œlarge reasoning models,” or LRMs, were still new. Nowadays it may seem downright churlish, though, given that a β€œgeneral-purpose reasoning model” from OpenAI solved a famous open mathematical…

Source

  •  

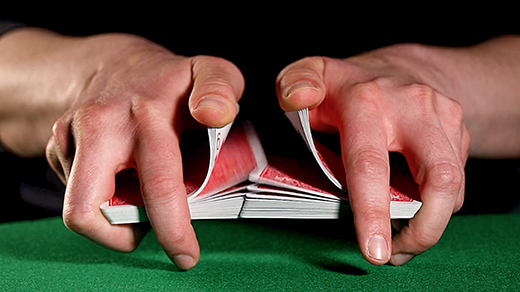
Seven Perfect Shuffles Randomize a Deck of Cards. But How Many Sloppy Ones?

In 1992, mathematicians famously proved that seven β€œriffle shuffles” β€” the kind where a player splits a deck of cards into two piles, then uses their thumbs to interleave them back together in a zipperlike motion β€” are enough to mix up the deck. When Dave Bayer and Persi Diaconis came up with this proof, they also revealed something surprising about what happens along the way: At first…

Source

  •  
❌